Skip to content
SCSky Coleman

Disaster recoveryBusiness continuityCyber resiliencyIncident response

I plan for the worst dayso the business survives it.

I'm Sky Coleman. 10+ years in enterprise IT and about 3 years of hands-on disaster recovery, the last 2 leading DR, business continuity, and cyber incident response at a Fortune 500 insurer. I also build with AI, and I run it with the same runbooks and verification a recovery program needs.

  • CompTIA Security+ ce badge
  • CompTIA CySA+ ce badge
  • CompTIA Security Analytics Professional badge

Verified on CredlyActive through Aug 2027

10+ years in enterprise IT

3 years of hands-on DR, the last 2 leading DR, BC and cyber IR at a Fortune 500 insurer

10,000+ servers in the patching and monitoring scope at Charter

3 CompTIA security certifications, each verifiable on Credly

Experience

Ten years of keeping infrastructure up. Two years of bringing it back.

From help desk to systems administration across universities, housing, telecom, and managed services, then into disaster recovery and cyber resiliency at a Fortune 500 insurer.

“His desire to learn, improve process, and ensure the server environment is healthy comes through within his work ethics. He would be an asset to any employer.”
From a recommendation letter signed by his Manager and Director at Charter Communications. Full letter available on request.

Education

University of North Carolina at Chapel Hill

Bachelor's degree, Communications (Media and Production), 2017

  1. The Hartfordvia Rose InternationalContract

    Apr 2024 to Dec 2025

    Cyber / Disaster Recovery and Resiliency Engineer

    • Led disaster recovery exercises and resiliency simulations across production and DR environments, aligned with compliance and resiliency requirements.
    • Supported cyber incident response: containment actions, forensic artifact collection, and coordinated recovery of business-critical services.
    • Drove the Business Continuity Management lifecycle: Business Impact Analysis, risk assessments, and recovery prioritization for critical business functions.
    • Built and maintained Business Continuity Plans and recovery documentation aligned with enterprise RTO and RPO targets.
    • Partnered with business units and IT owners on tabletop exercises, resiliency assessments, and post-DR validation.
    • Wrote findings reports with recommended improvements, and delivered documentation and training that strengthened resiliency culture.
    • DR exercises
    • Cyber IR
    • BIA
    • BCP
    • RTO / RPO
    • Tabletops
  2. Charter Communications / SpectrumContract

    Oct 2023 to Mar 2024

    System Administrator

    • Patched and monitored servers through an enterprise endpoint management platform spanning 10,000+ servers, on a team that owned 4,000+ Windows servers.
    • Supported and administered virtualization platforms; deployed, configured, and maintained Windows servers.
    • Worked alerts, vendor hardware and OS fixes, and server decommissioning with application, data center, and database teams.
    • Endpoint management
    • Patch management
    • Virtualization
    • Windows servers
  3. Inlivian Housing Authority

    Jun 2023 to Oct 2023

    System Administrator

    • One of a team of 4 supporting 45 sites for network and endpoint troubleshooting.
    • Ran IAM and access-control provisioning; administered firewalls, network hardware, and the intranet.
    • Installed and serviced access control, intrusion alarms, and CCTV. Administered cloud email and collaboration security policies and voice.
    • IAM
    • Firewalls
    • Physical security
    • Cloud collaboration
  4. Internet Services Corporation

    Mar 2022 to May 2023

    Systems and Network Administrator

    • Deployed enterprise switches, routers, and firewalls; engineered IPsec tunnels for multiple remote locations.
    • Ran server administration, backups, and disaster recovery on a backup appliance (directory, DNS, web, clustering, virtualization).
    • Built production VMs on hyperconverged infrastructure, managed PKI certificates for web, VPN, and virtual servers, and audited systems for policy compliance.
    • Disaster recovery
    • Backup and restore
    • Firewalls
    • IPsec VPN
    • Hyperconverged
    • PKI
  5. University of North Carolina

    Jul 2017 to Feb 2022

    Systems Administrator

    • Implemented site-wide multi-factor authentication and mobile device management.
    • Managed directory security groups, group policy, OUs, and domain controllers; automated patch deployment.
    • Ran the virtualization environment, and monitored firewalls, VPN gateways, intrusion detection, and the SIEM.
    • Supported replay and A/V systems for UNC Basketball and Football game days.
    • MFA
    • Device management
    • Directory services
    • Patch automation
    • Virtualization
    • SIEM

Interactive tabletop

Run a recovery drill.

Pick an incident and watch the recovery play out against its RTO and RPO targets, the way I would walk a room of app owners through a tabletop. Generic scenarios, not any employer's plan.

Ransomware in the primary data center

Tier 1 claims platform

RTO

4h

RPO

15m

Clock

T+0m

RTO target
UsersservedreplicatingPrimary data centerHealthyDR siteStandby
  1. 1Detect·EDR and SIEM alerts fireT+0m
  2. 2Declare·Disaster declaredT+12m
  3. 3Contain·Isolate the blast radiusT+25m
  4. 4Recover·Recover from clean backupsT+1h 10m
  5. 5Validate·Business sign-off and cutoverT+2h 30m
  6. 6Learn·Restored inside RTOT+3h 25m
  7. Press Start drill. You can pause or step through it.

AI systems

I run AI like a production environment.

Over the past year I built a multi-agent engineering setup that ships real software for real people. What makes it trustworthy is the controls around it: change gates, guardrails, verification, and postmortems. Those are the same things that make a DR program work.

Intent · Me

I own the decision: scope, risk, and what done means. Irreversible actions, money, and anything public stay gated on a human.

specialized agents
25specialized agents
custom skills, written like runbooks
35custom skills, written like runbooks
guardrail and automation hooks
11guardrail and automation hooks
standing rules, each traced to a real incident
79standing rules, each traced to a real incident

Models from more than one vendor, custom tool servers I wrote for the agents, and local models on my own GPU. This site was rebuilt with the same stack and went through the same checks before it shipped.

Case studies

Problem, action, result. Written the way I write findings reports.

01 · Security audit

Locked down a multi-tenant database serving about 25 apps

A shared database project had 202 tables with row-level security switched off. Anyone holding the public client key, which ships inside every web and mobile app, could read and write them.

202

tables exposed

244

tables probed per run

3

client identities tested

What I did

  1. 1.Mapped which tables real client code actually needed, so the fix would not take production apps down.
  2. 2.Shipped one migration that enabled row-level security everywhere, with a short allow-list of deliberate exceptions.
  3. 3.Wrote a probe that tests all 244 tables as every client identity (anonymous, public key, signed-in user) and re-runs after any policy change.

Closed the exposure without breaking a single server-side pipeline, and turned a one-time fix into a repeatable control.
02 · Change control

Turned a near-miss deploy into a permanent preflight

An agent redeployed an old app over a live pitch deck because the project docs were stale. It was recoverable, but it was a change made on trust instead of evidence.

20+

sites covered

2

checks per deploy

1

rule, loaded every session

What I did

  1. 1.Ran it like a postmortem. Root cause: reading the record instead of the thing.
  2. 2.Built a deploy guardrail that checks what a URL serves right now before anything overwrites it, then updates the deploy map in the same step.
  3. 3.Applied it to every deploy across 20+ sites, not just the one that failed.

That class of mistake has a control in front of it now. Same idea as validating a DR runbook against production, not against last year's diagram.

03 · Resilient design

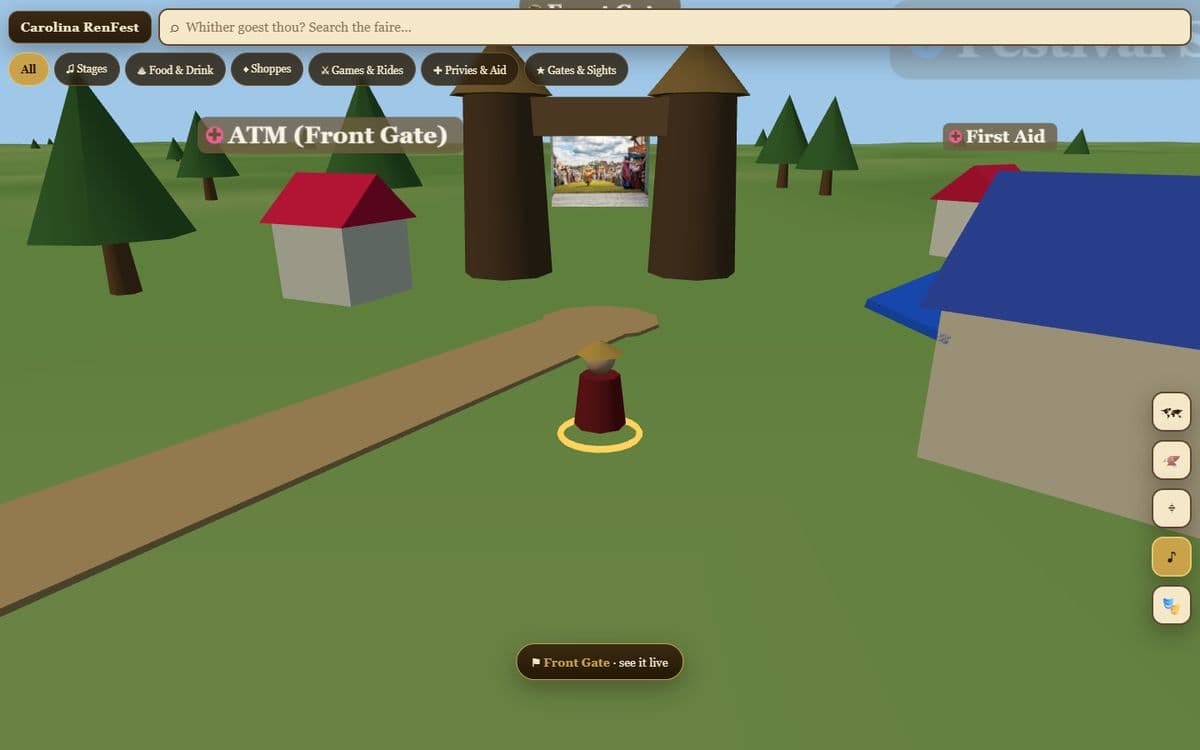
A 3D venue map that keeps working with no signal

A fairground with a couple hundred thousand guests a season has almost no usable cell service, so a normal web app fails exactly when people need it.

0

bars of signal needed

2

venues in one build

A*

routing on the device

What I did

  1. 1.Turned a flat 2D venue map into a navigable 3D world with search and turn-by-turn routing.
  2. 2.Designed for the failure case first: an offline-first web app that caches everything it needs on the first load.
  3. 3.Added a GPS you-are-here marker that degrades gracefully when location is unavailable.

Live at faireway.app. The whole product is a continuity plan: assume the network is gone and still get people where they are going.

Toolkit

What I have actually run, at work and in my own stack.

Frameworks I work to

  • NIST SP 800-34

    Contingency planning: BIA method, recovery strategies, plan testing

  • ISO 22301

    Business continuity management: BIA, continuity strategies, exercising

  • NIST CSF 2.0

    Respond and Recover functions: incident handling, recovery planning, communications

  • NIST SP 800-61 Rev. 3

    Incident response recommendations, organized around the CSF 2.0 functions

  • FFIEC BCM booklet

    Business continuity expectations for banks and financial institutions

  • HSEEP

    Exercise design, conduct, and after-action reporting

Resiliency and security

  • Business Impact Analysis
  • Business Continuity Plans
  • DR testing and exercises
  • RTO / RPO design
  • Tabletop exercises
  • Cyber incident response
  • Forensic artifact collection
  • SIEM monitoring
  • IAM and MFA
  • Patch and vulnerability management
  • Access-control and compliance audits
  • Risk assessments

Infrastructure

  • Windows and Linux servers
  • Directory services and group policy
  • Virtualization
  • Hyperconverged infrastructure
  • Backup and restore
  • Endpoint management at scale
  • Mobile device management
  • Firewalls and VPN
  • Switching, routing, VLANs
  • PKI and certificates
  • ITSM ticketing
  • Public cloud

Automation and AI

  • Scripting and automation
  • Query and reporting
  • Multi-agent orchestration
  • Custom tool servers for agents
  • Agent guardrails
  • Local models on GPU
  • Cross-model review
  • Web and mobile apps
  • Managed databases
  • Deploy pipelines

Contact

Hiring for DR, continuity, or cyber resiliency? Let's talk.

Open to remote roles, full-time or contract, starting immediately. I reply to every message.

Email me